Logfire has the most advanced Fleet Management for OpenTelemetry in the Observability industry, covering both OTel Collectors and SDKs.
Fleet management for your Collectors and apps
Instrument every service and every host, then decide in one place what each of them samples, scrubs and sends. Sampling rules, rate caps and secret scrubbing apply inside running applications, and Collector pipelines change without SSH sessions or redeploys. Everything connects over OpAMP, the open protocol for managing telemetry agents.
Trusted by teams building production software and AI
Definition
What is fleet management for telemetry?
Every machine runs a Collector and every service runs an SDK, and each has a configuration that decides what is collected, what is dropped and
where it goes. Fleet management moves that configuration out of a thousand files and into one place, where you can change it, roll it out, and
see which agents are actually running it.
In Logfire, each agent keeps a connection open over OpAMP, reports its health and effective configuration, and applies the
policy you publish. That reaches inside your applications too: the sampling rate, the volume caps and what gets scrubbed are settings you change
from Logfire, not code you redeploy.
One control plane
Applications, hosts and clusters, side by side
Applications
Python, Node.js, Go, Java and .NET services connect with a small OpAMP client beside their OpenTelemetry SDK. An application policy changes sampling, rate caps, exports, log levels, redaction and scrubbing inside the running process.
Collectors on hosts
A standard OpenTelemetry Collector build, run by an OpAMP Supervisor on Linux, macOS or Windows. Fleet owns its whole configuration: what it collects from the machine, what the local apps send it, and where it all goes.
Kubernetes
The OpenTelemetry Operator's OpAMP bridge connects a cluster. A Kubernetes policy describes the Collector workloads (deployments and daemonsets) and the Operator creates, updates or removes them to match.
Application policies
Sample, scrub and cap telemetry inside every service
Instrumenting everything is only affordable when you can turn it down. The noisiest health-check endpoint, the trace rate that was fine until
launch day, the attribute that should never have been exported: in most setups each is a code change and a redeploy in every service that has
it. With an application policy it is one published version that running processes in Python, Node.js, Go, Java and .NET pick up without a
redeploy.
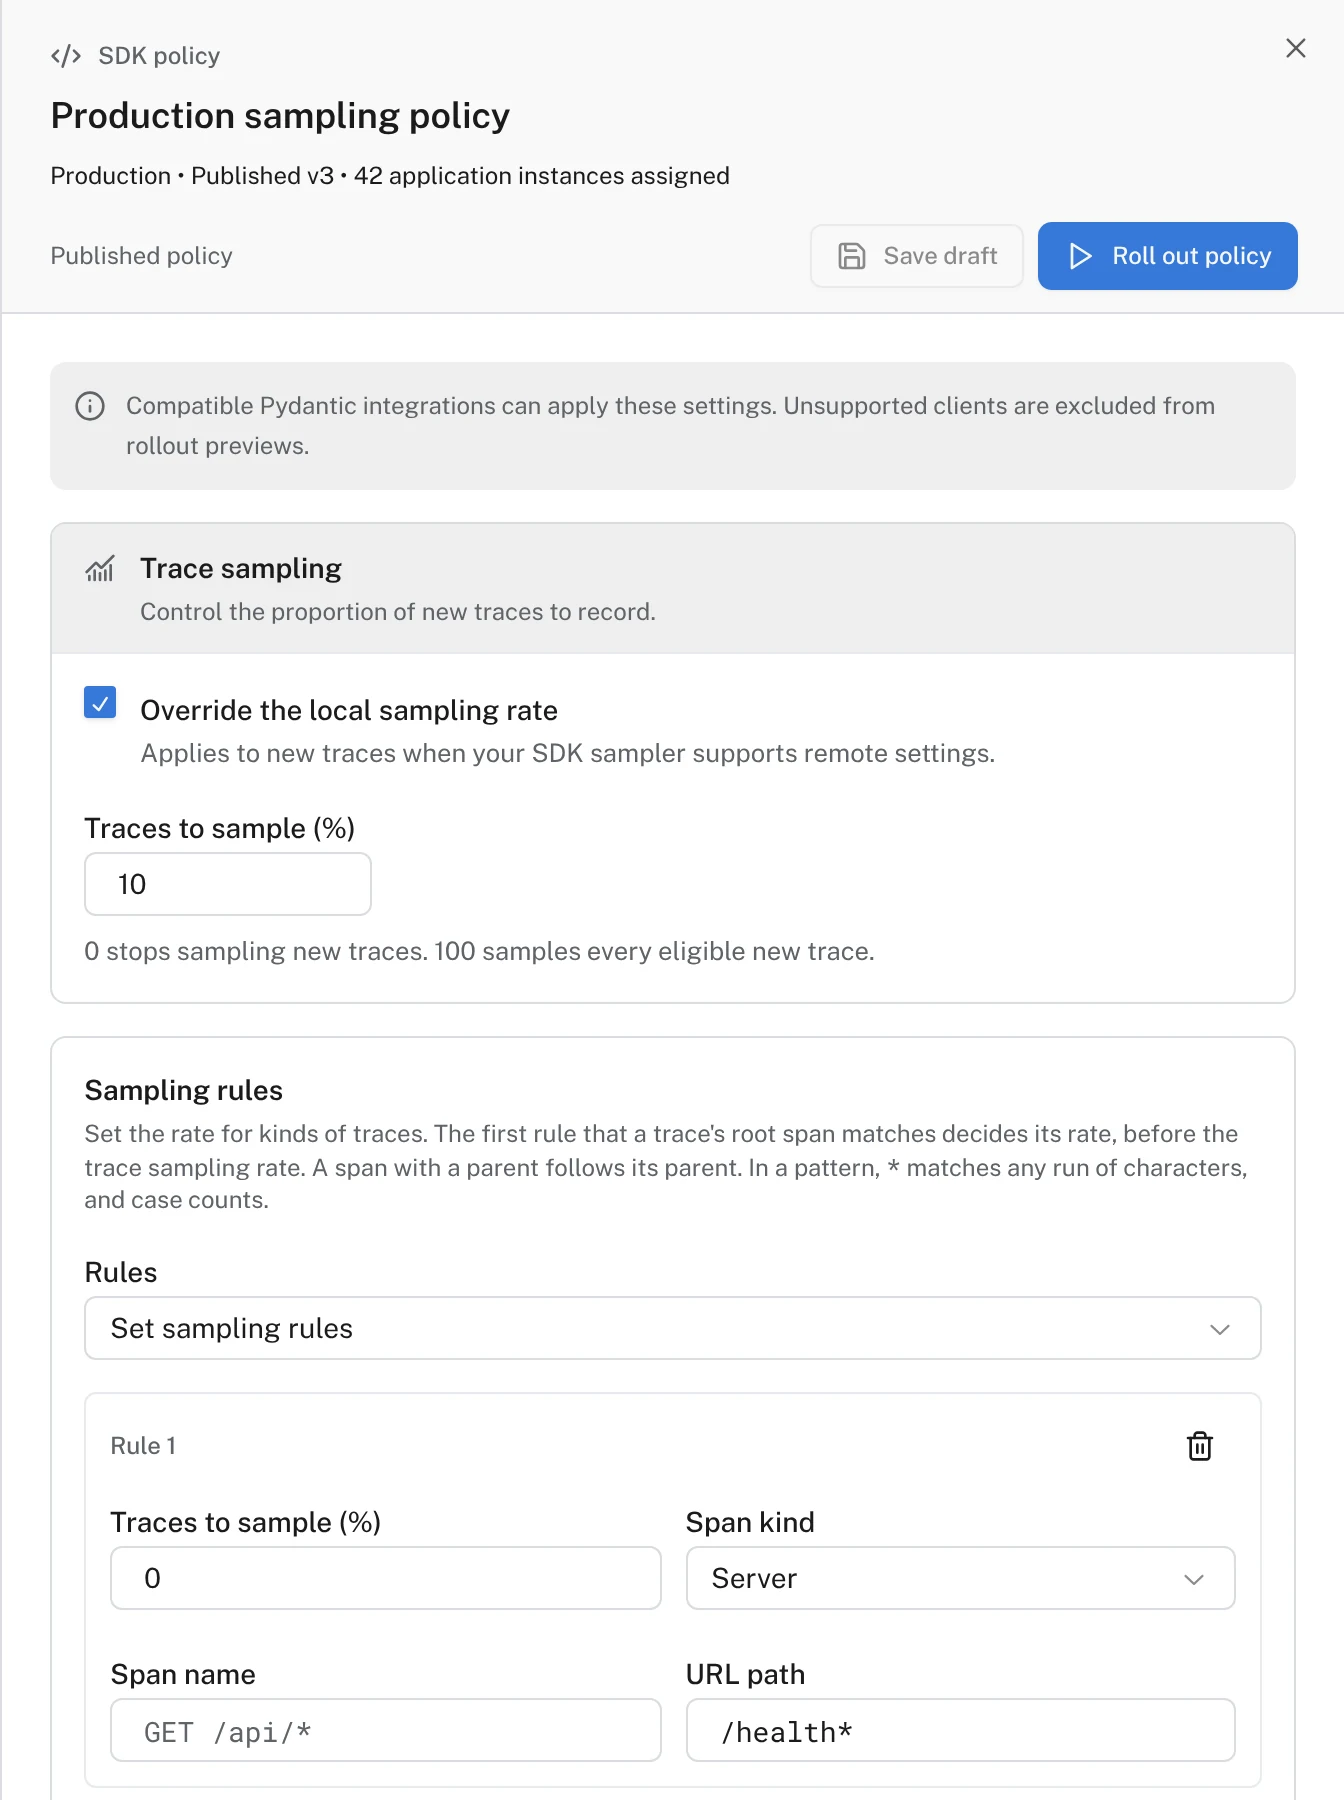
Sampling rules per route
Set a head sampling rate for new traces, then put ordered rules in front of it that match a root span by name, kind, URL path or attributes. Drop health checks, keep every checkout, sample the rest at 10 percent. Child spans follow their parent's decision, so the traces you keep stay whole.
Hard caps on volume
Cap traces per second and log records per second in each process, set the minimum log level per logger, or pause a signal's exports outright. A release that starts logging in a loop runs into the cap before it runs up the bill.
Secrets scrubbed in the process
Turn on the Logfire SDK's default scrubbing in every language, which catches values under names like password, api_key, credential, session, cookie, jwt and credit_card, and add patterns of your own. Mask or drop attributes by key. Policy scrubbing runs at export on the exporters the policy governs, so an attribute added before export is still caught, and it adds to whatever the SDK scrubs locally rather than replacing it.
One decision for every destination
In Python, Node.js, Java and .NET, a policy governs every exporter the SDK sends through, whether it points at Logfire, another OTLP backend or the console. Each span and log record is decided once and each of those destinations receives the same result, so a second backend never sees the secret or the volume the first one was spared. An export path the client cannot gate, such as a custom processor of your own, is reported as ungoverned.
One policy across 42 instances: health checks dropped, half of GET /api/* kept, everything else sampled at 10 percent. Each process reports whether every setting applied.
Collector policies
Build the pipeline on a canvas, keep the YAML
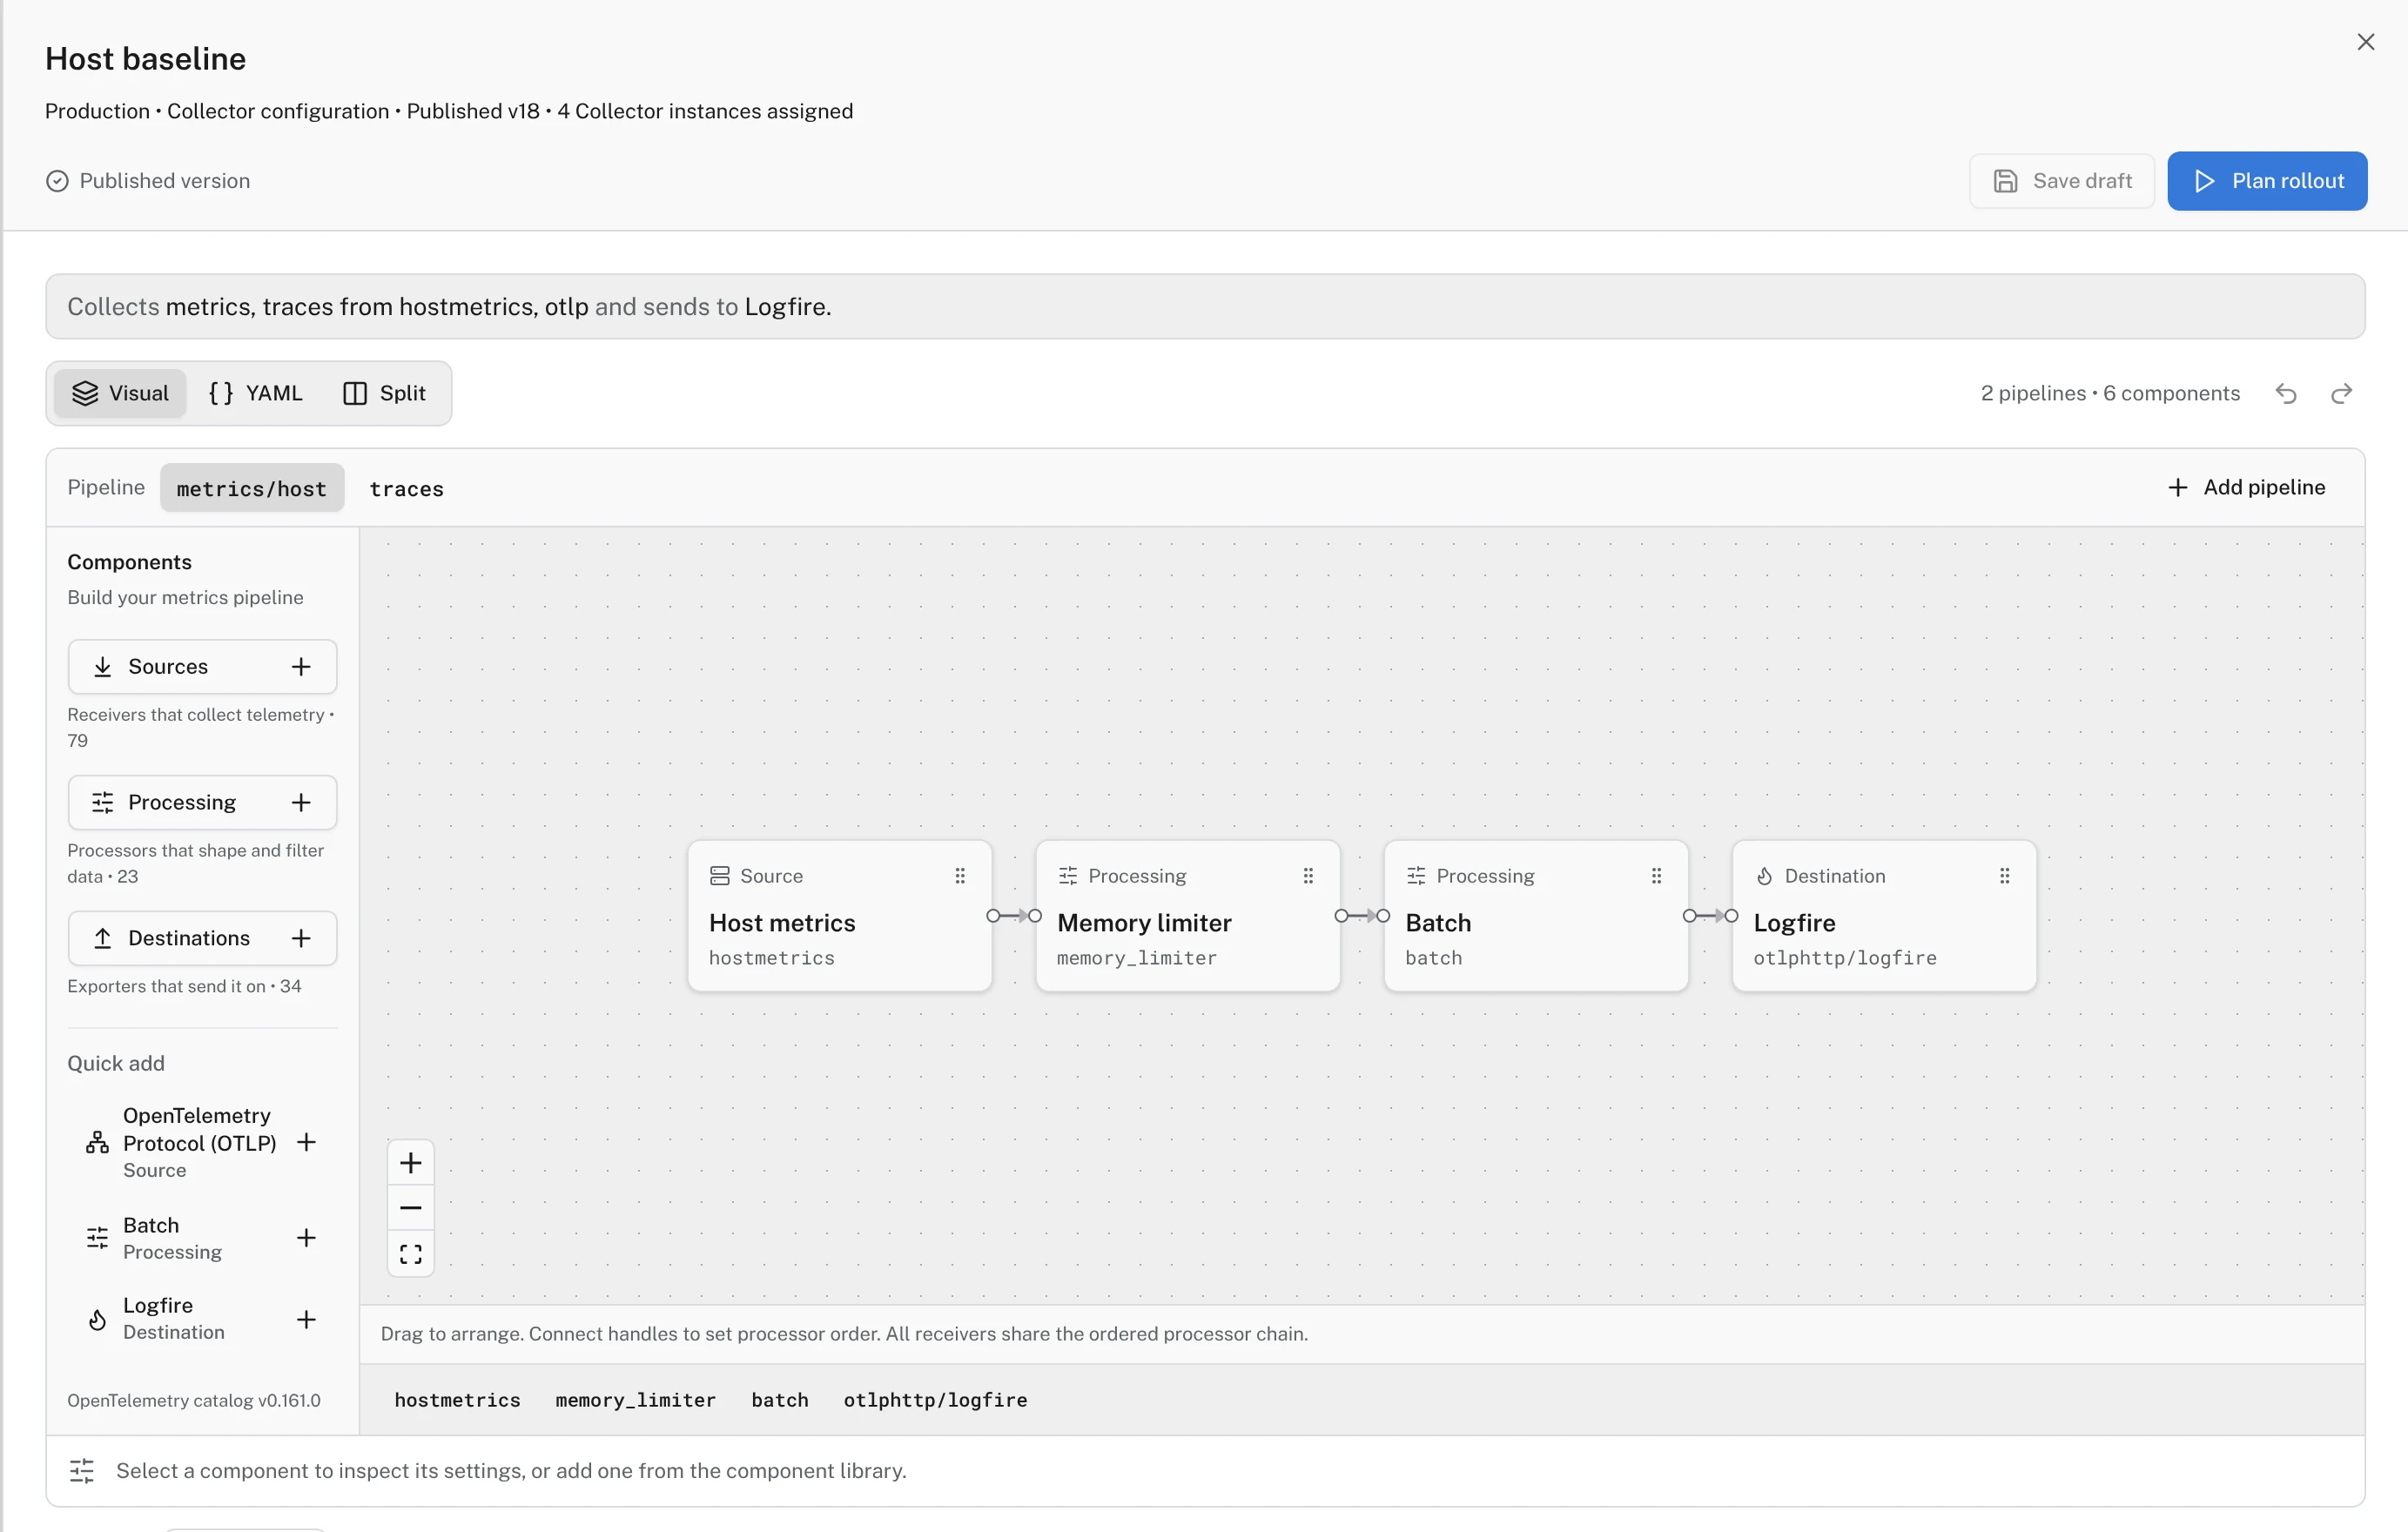
A Collector policy is a Collector configuration. Edit it as a pipeline of sources, processing and destinations, as YAML, or both at once in
Split view: they are the same document, and comments survive the round trip.
Templates for Linux, Windows and macOS hosts, file logs, Prometheus scraping and application OTLP give you a working start. The component library lists upstream receivers, processors and exporters, and common settings get a form instead of a blank YAML block.
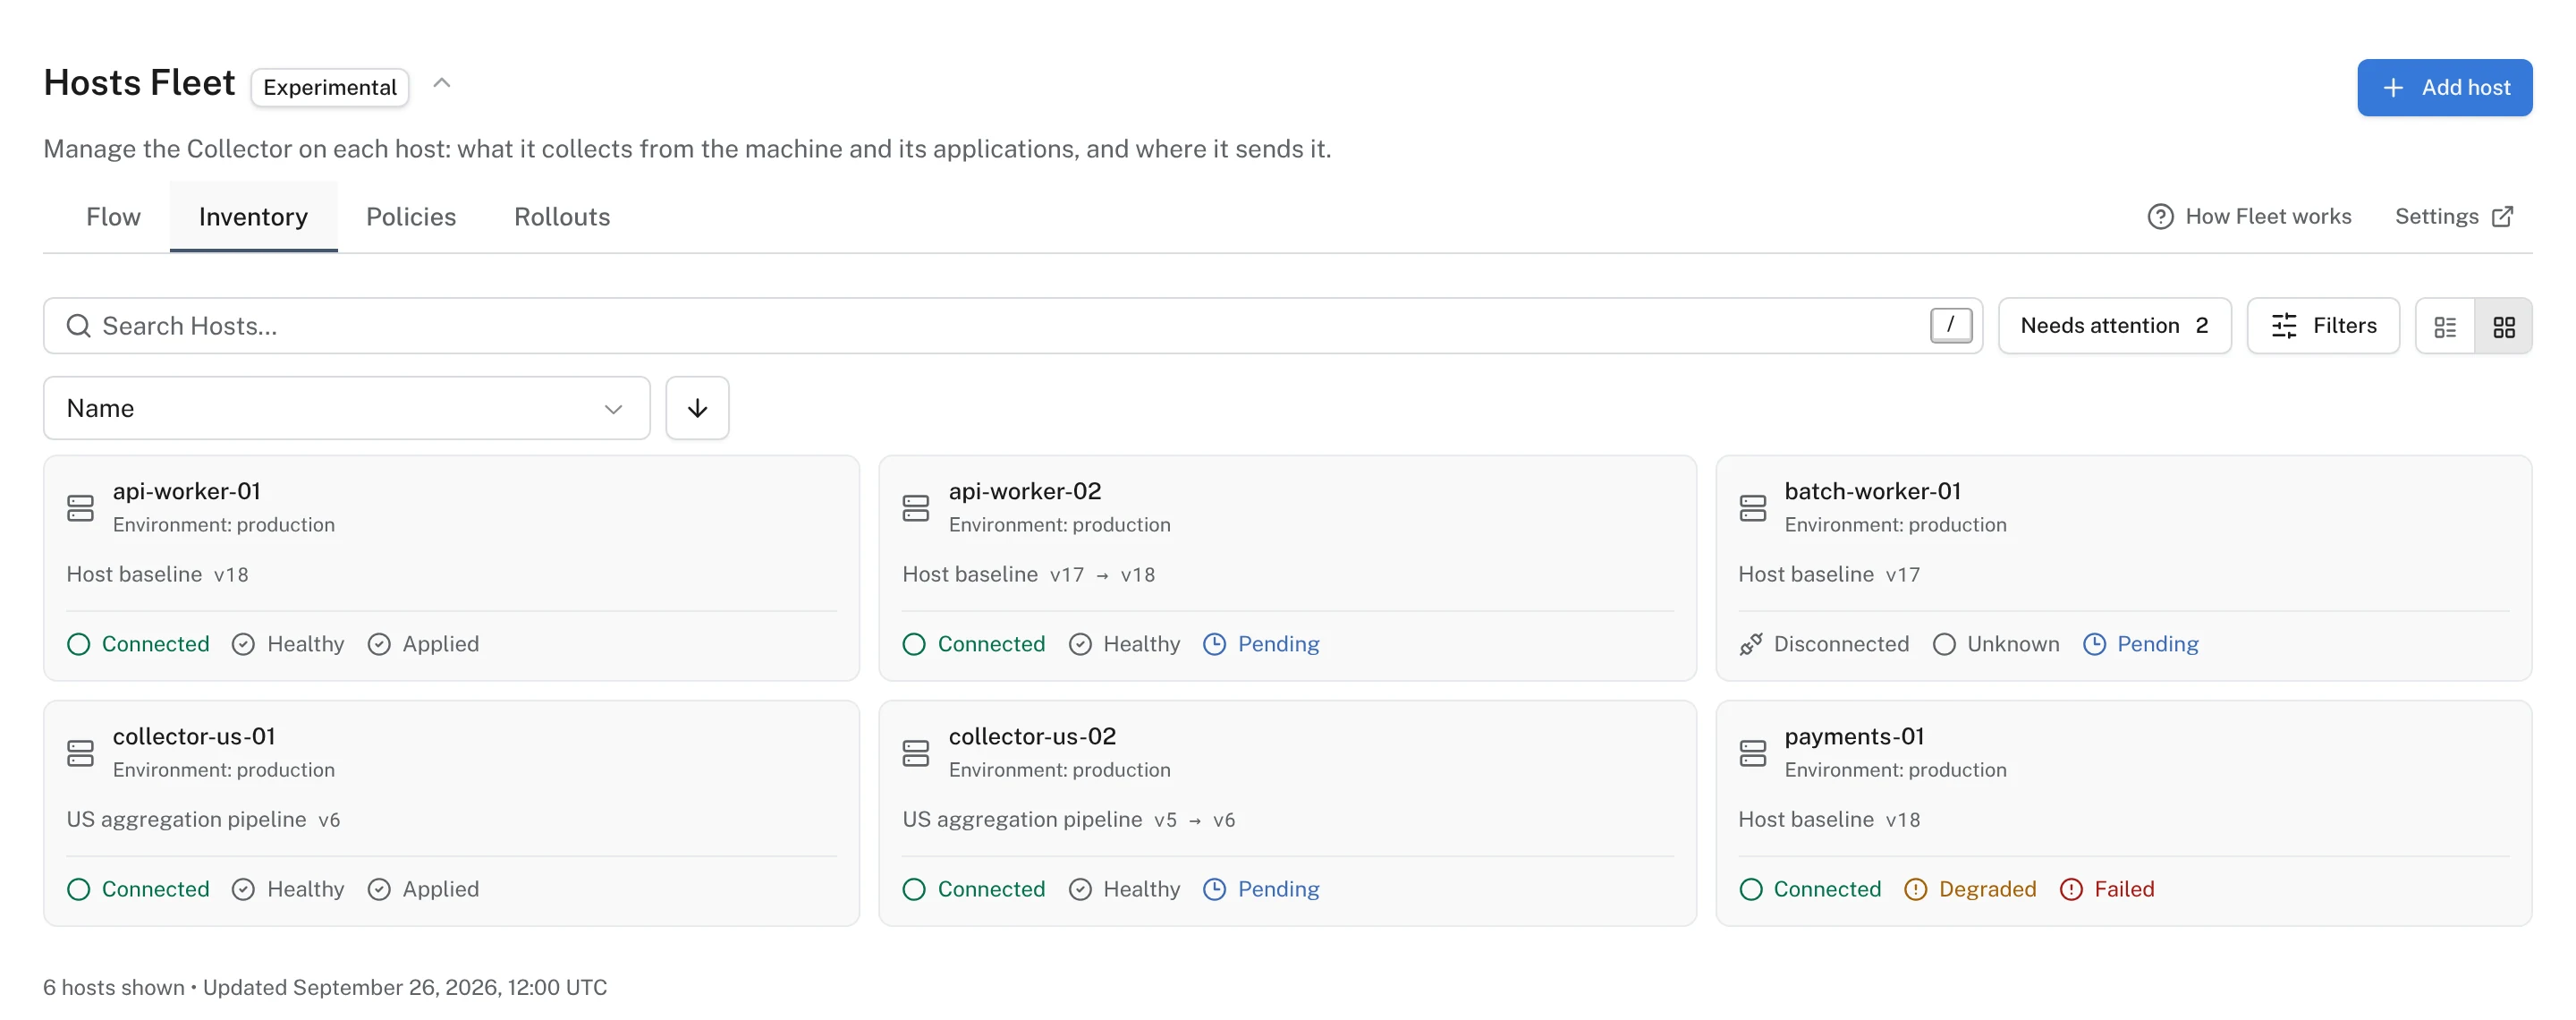
Each Collector reports its connection, its health and whether the latest version applied. A host that failed to apply version 18 shows as failed, with its component health and the error, instead of silently running version 17.
Try it on your stack
Put one host under management
Start free, then connect your first host from the Fleet page in Logfire.
Collectors in your cluster, through the OpenTelemetry Operator
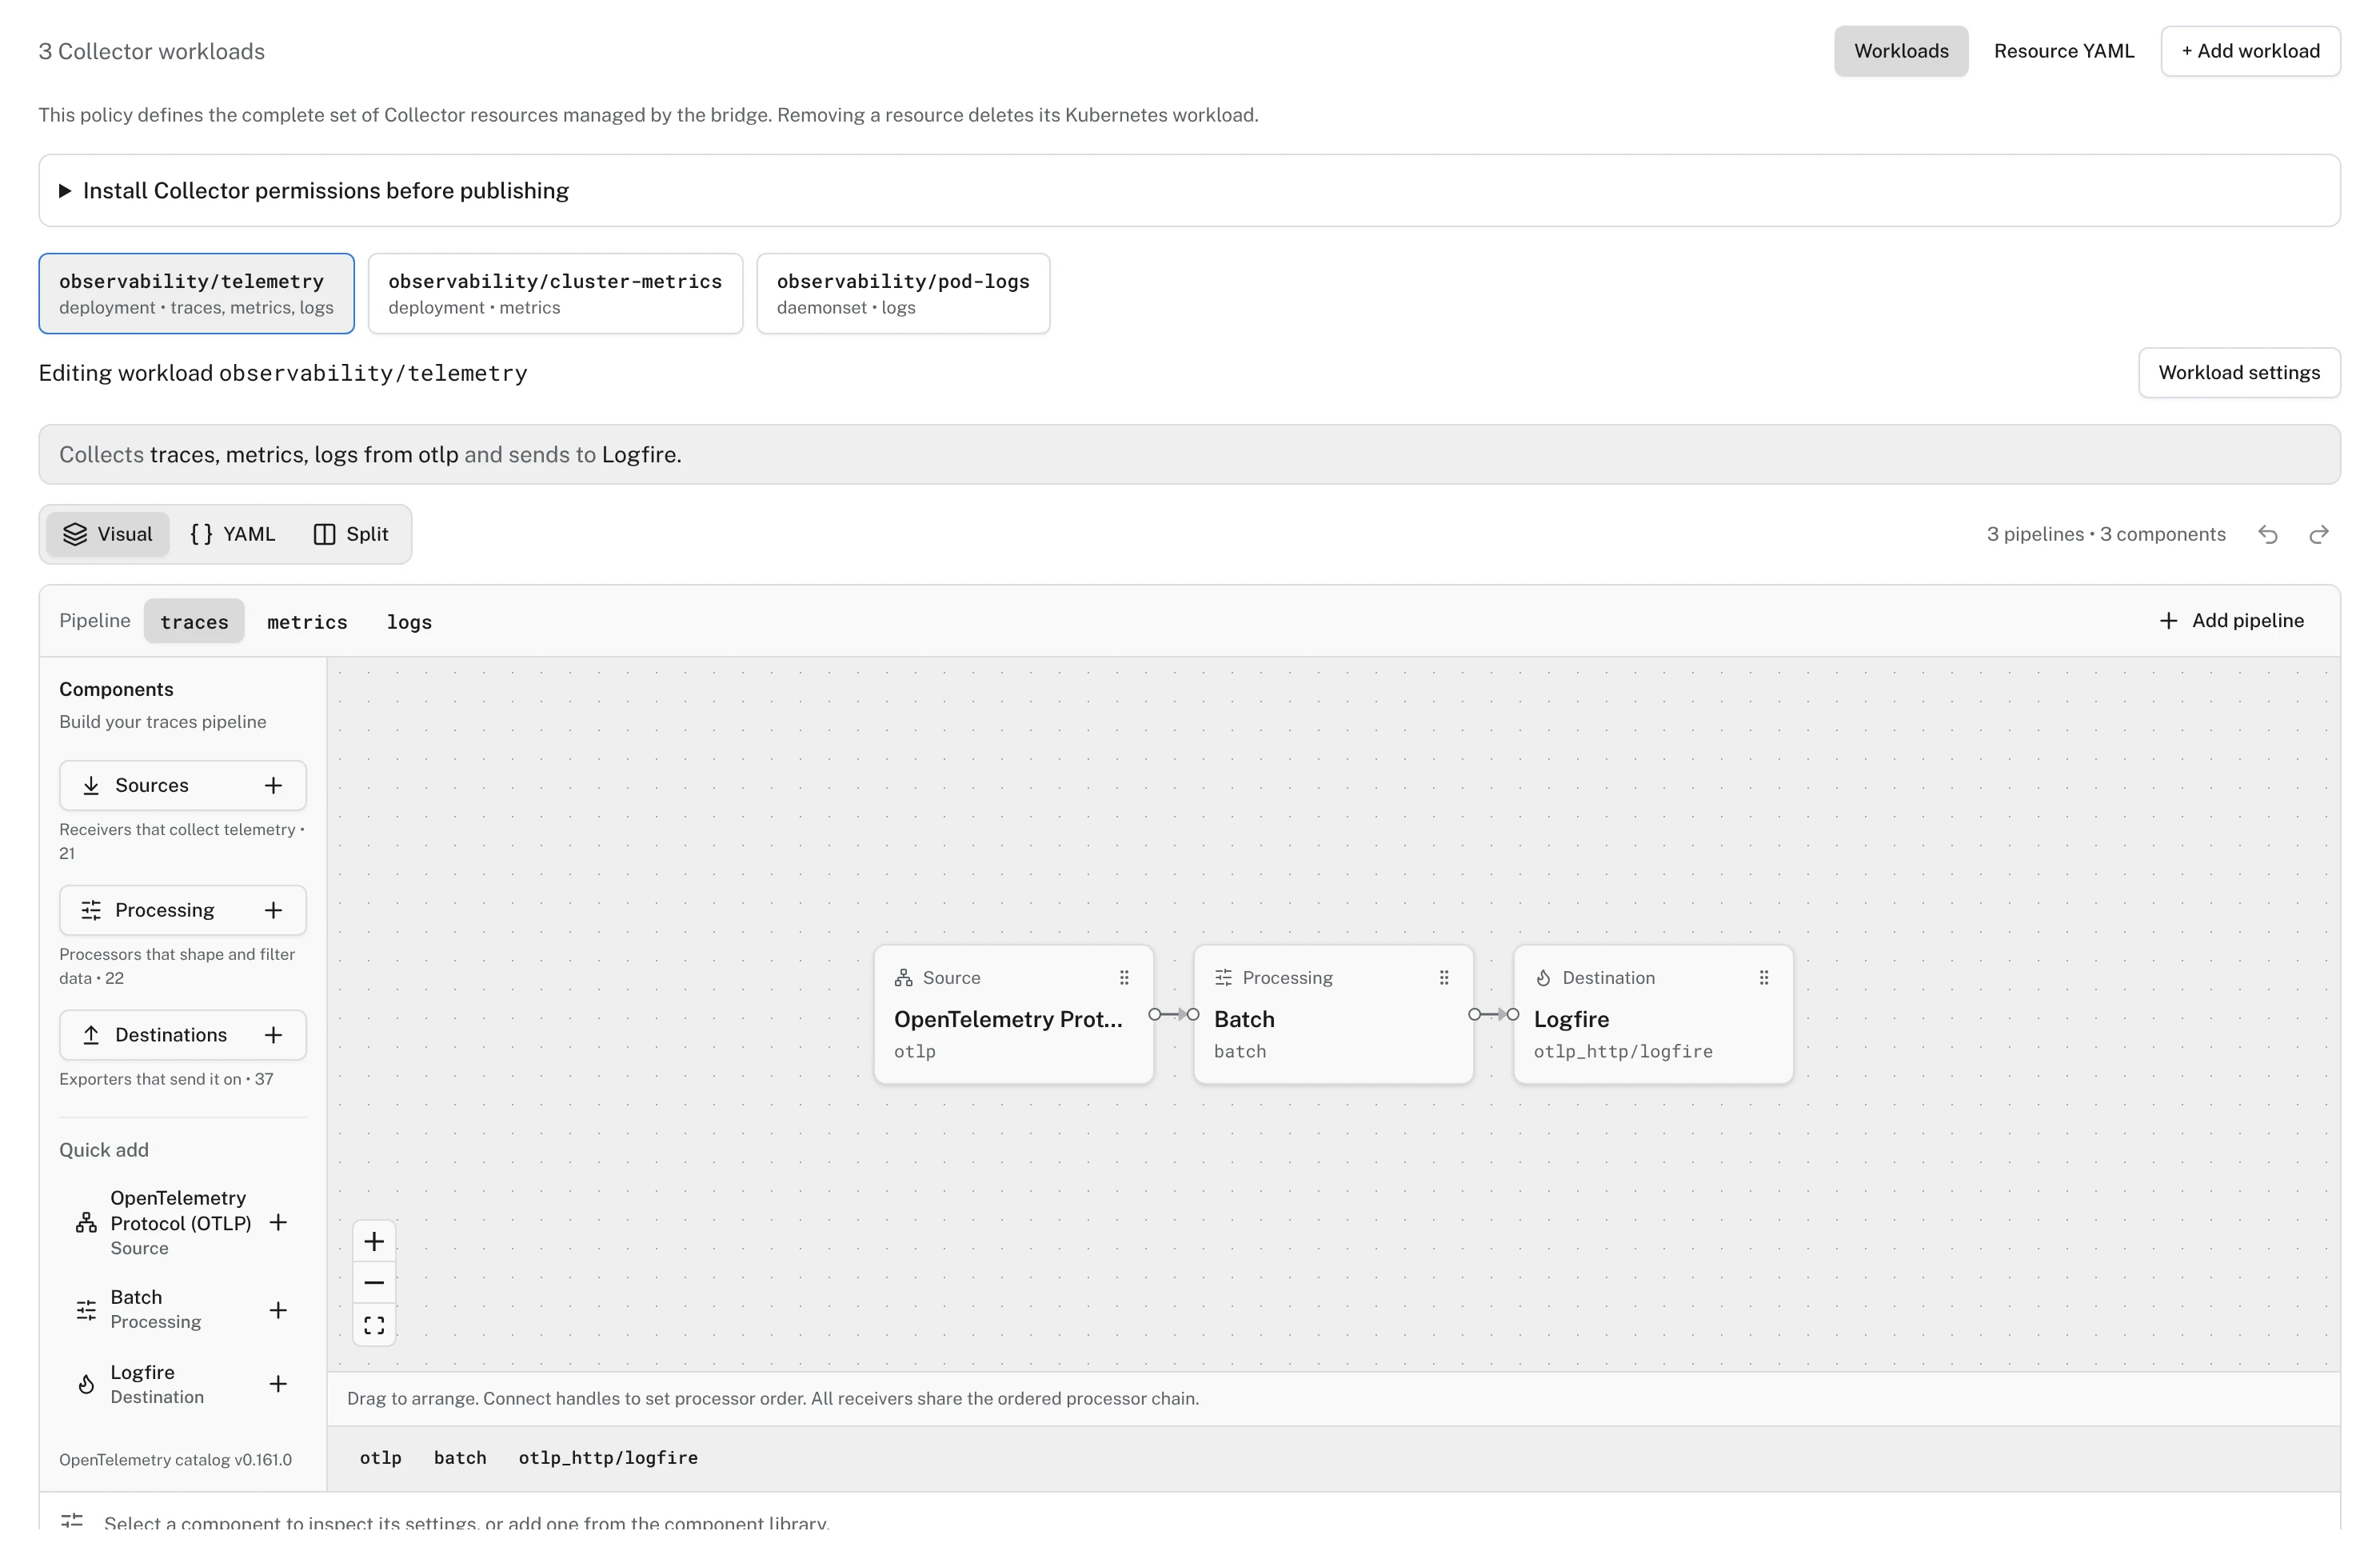
Install the OpenTelemetry Operator and its OpAMP bridge, then manage the cluster's Collectors from Logfire. A Kubernetes policy lists the
Collector workloads it wants and the Operator makes the cluster match: add one, edit its pipeline, or remove it.
Starting points for application telemetry, cluster metrics and pod logs. Each workload has the same visual and YAML editor as a host policy, plus its Kubernetes settings.
Safe rollouts
Change a thousand Collectors one decision at a time
Drafts touch nothing
Save as many drafts as you like. A Collector or application only changes when someone publishes a version, so a half-finished edit never reaches production because a tab was left open.
Review the diff, then publish
Publishing opens a review of exactly what changes against the running version: the YAML diff for a Collector, the changed settings for an application policy, and how many clients it will reach.
Pilot on a few, then the rest
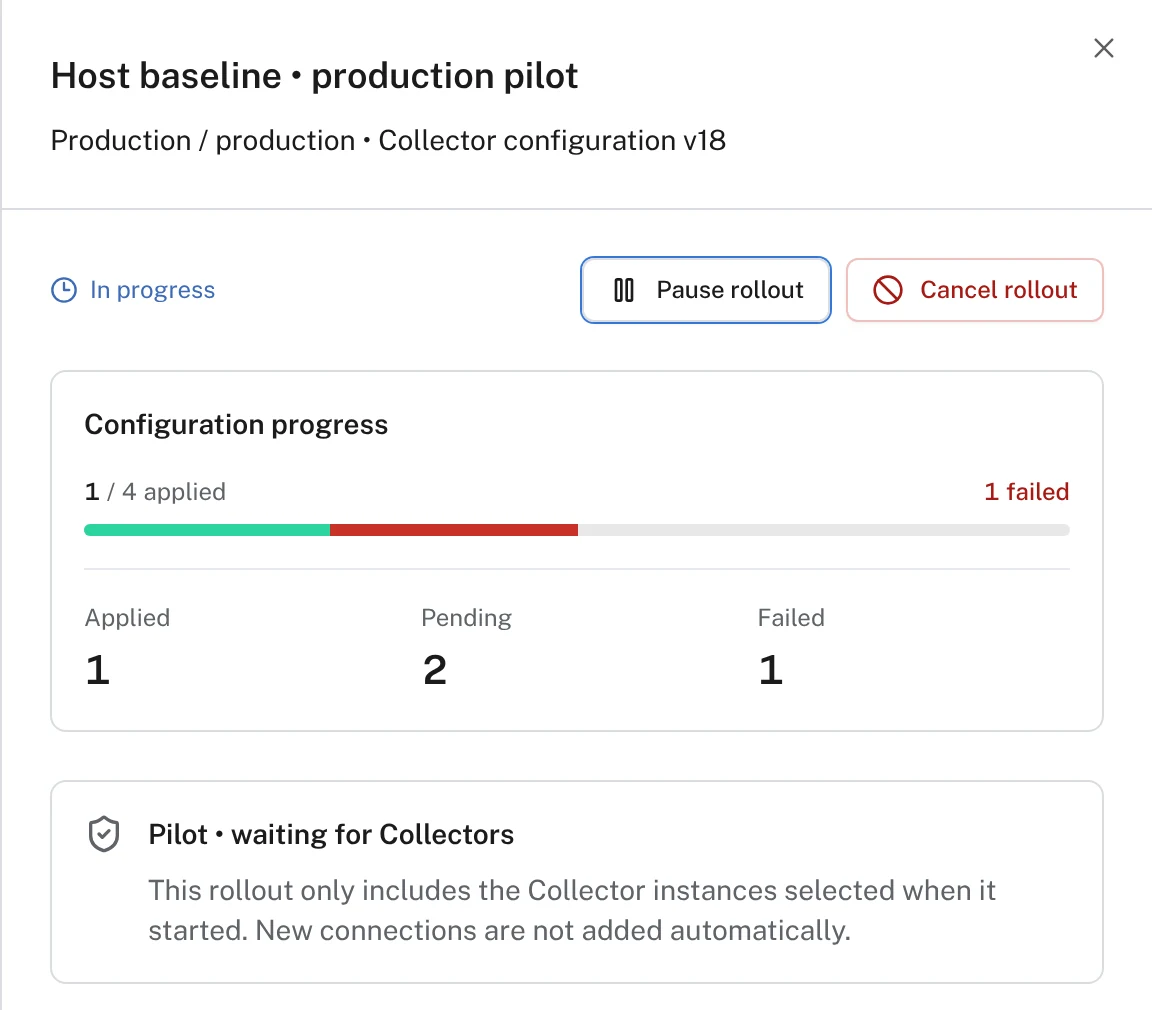
Turn on rollouts and a new version goes to the Collectors you pick first. Progress shows applied, pending and failed per client. Pause stops further sends; cancel ends the rollout.
Roll back from history
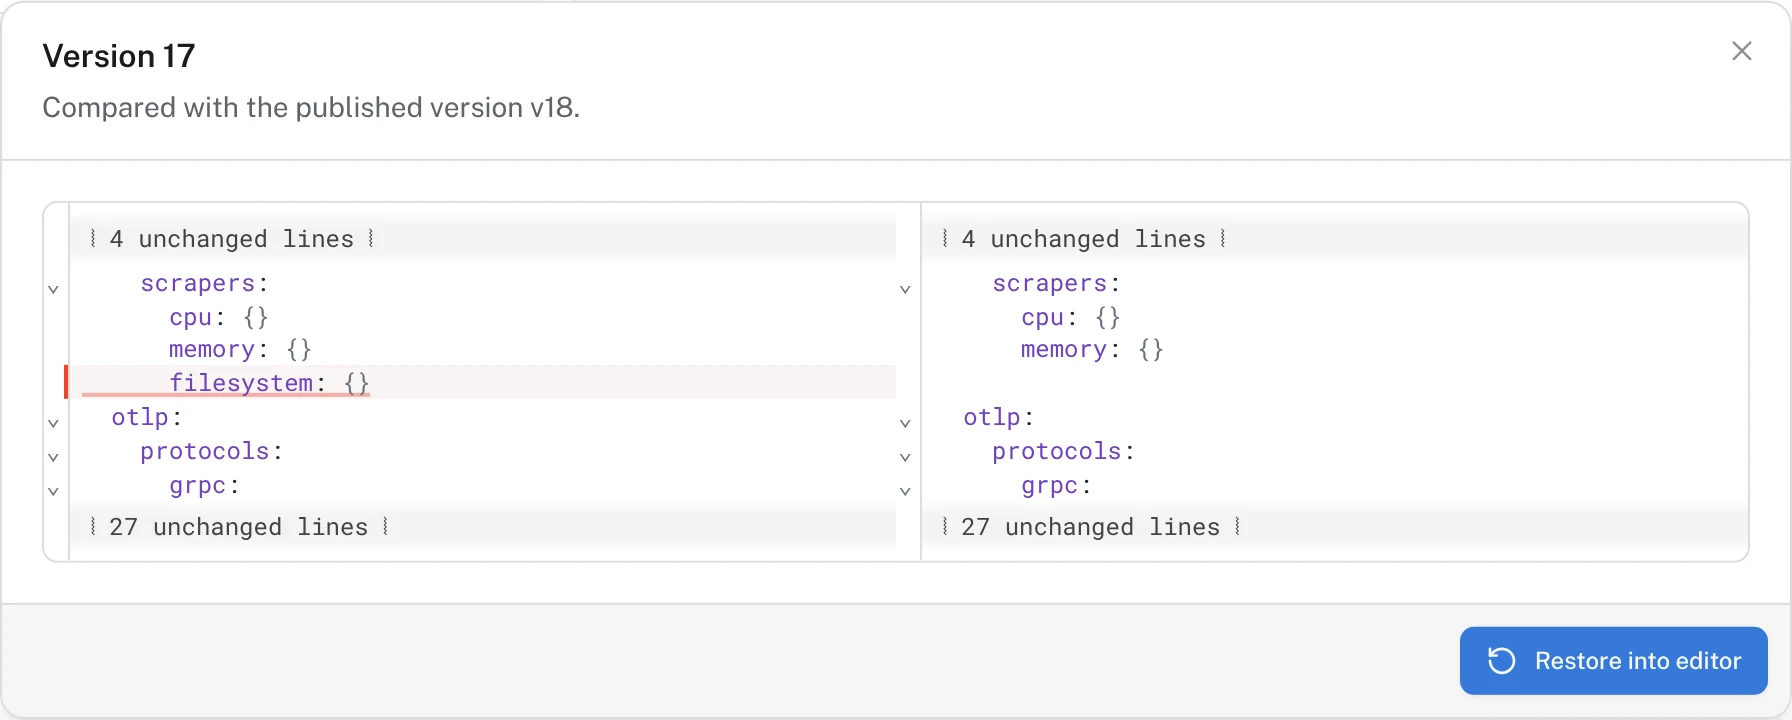
Every published version is kept. Open an earlier one as a diff, restore it into the editor, and publish it again as the next version. The history stays linear, so the audit trail shows the rollback too.
A pilot rollout of version 18 to four production hosts. One failed, so the rollout can be paused before the version goes any further, and the failing host's detail shows why.
Any earlier version opens as a diff against the published one. Restore it into the editor and publish it to roll back.
Traffic
See which Collectors send the most
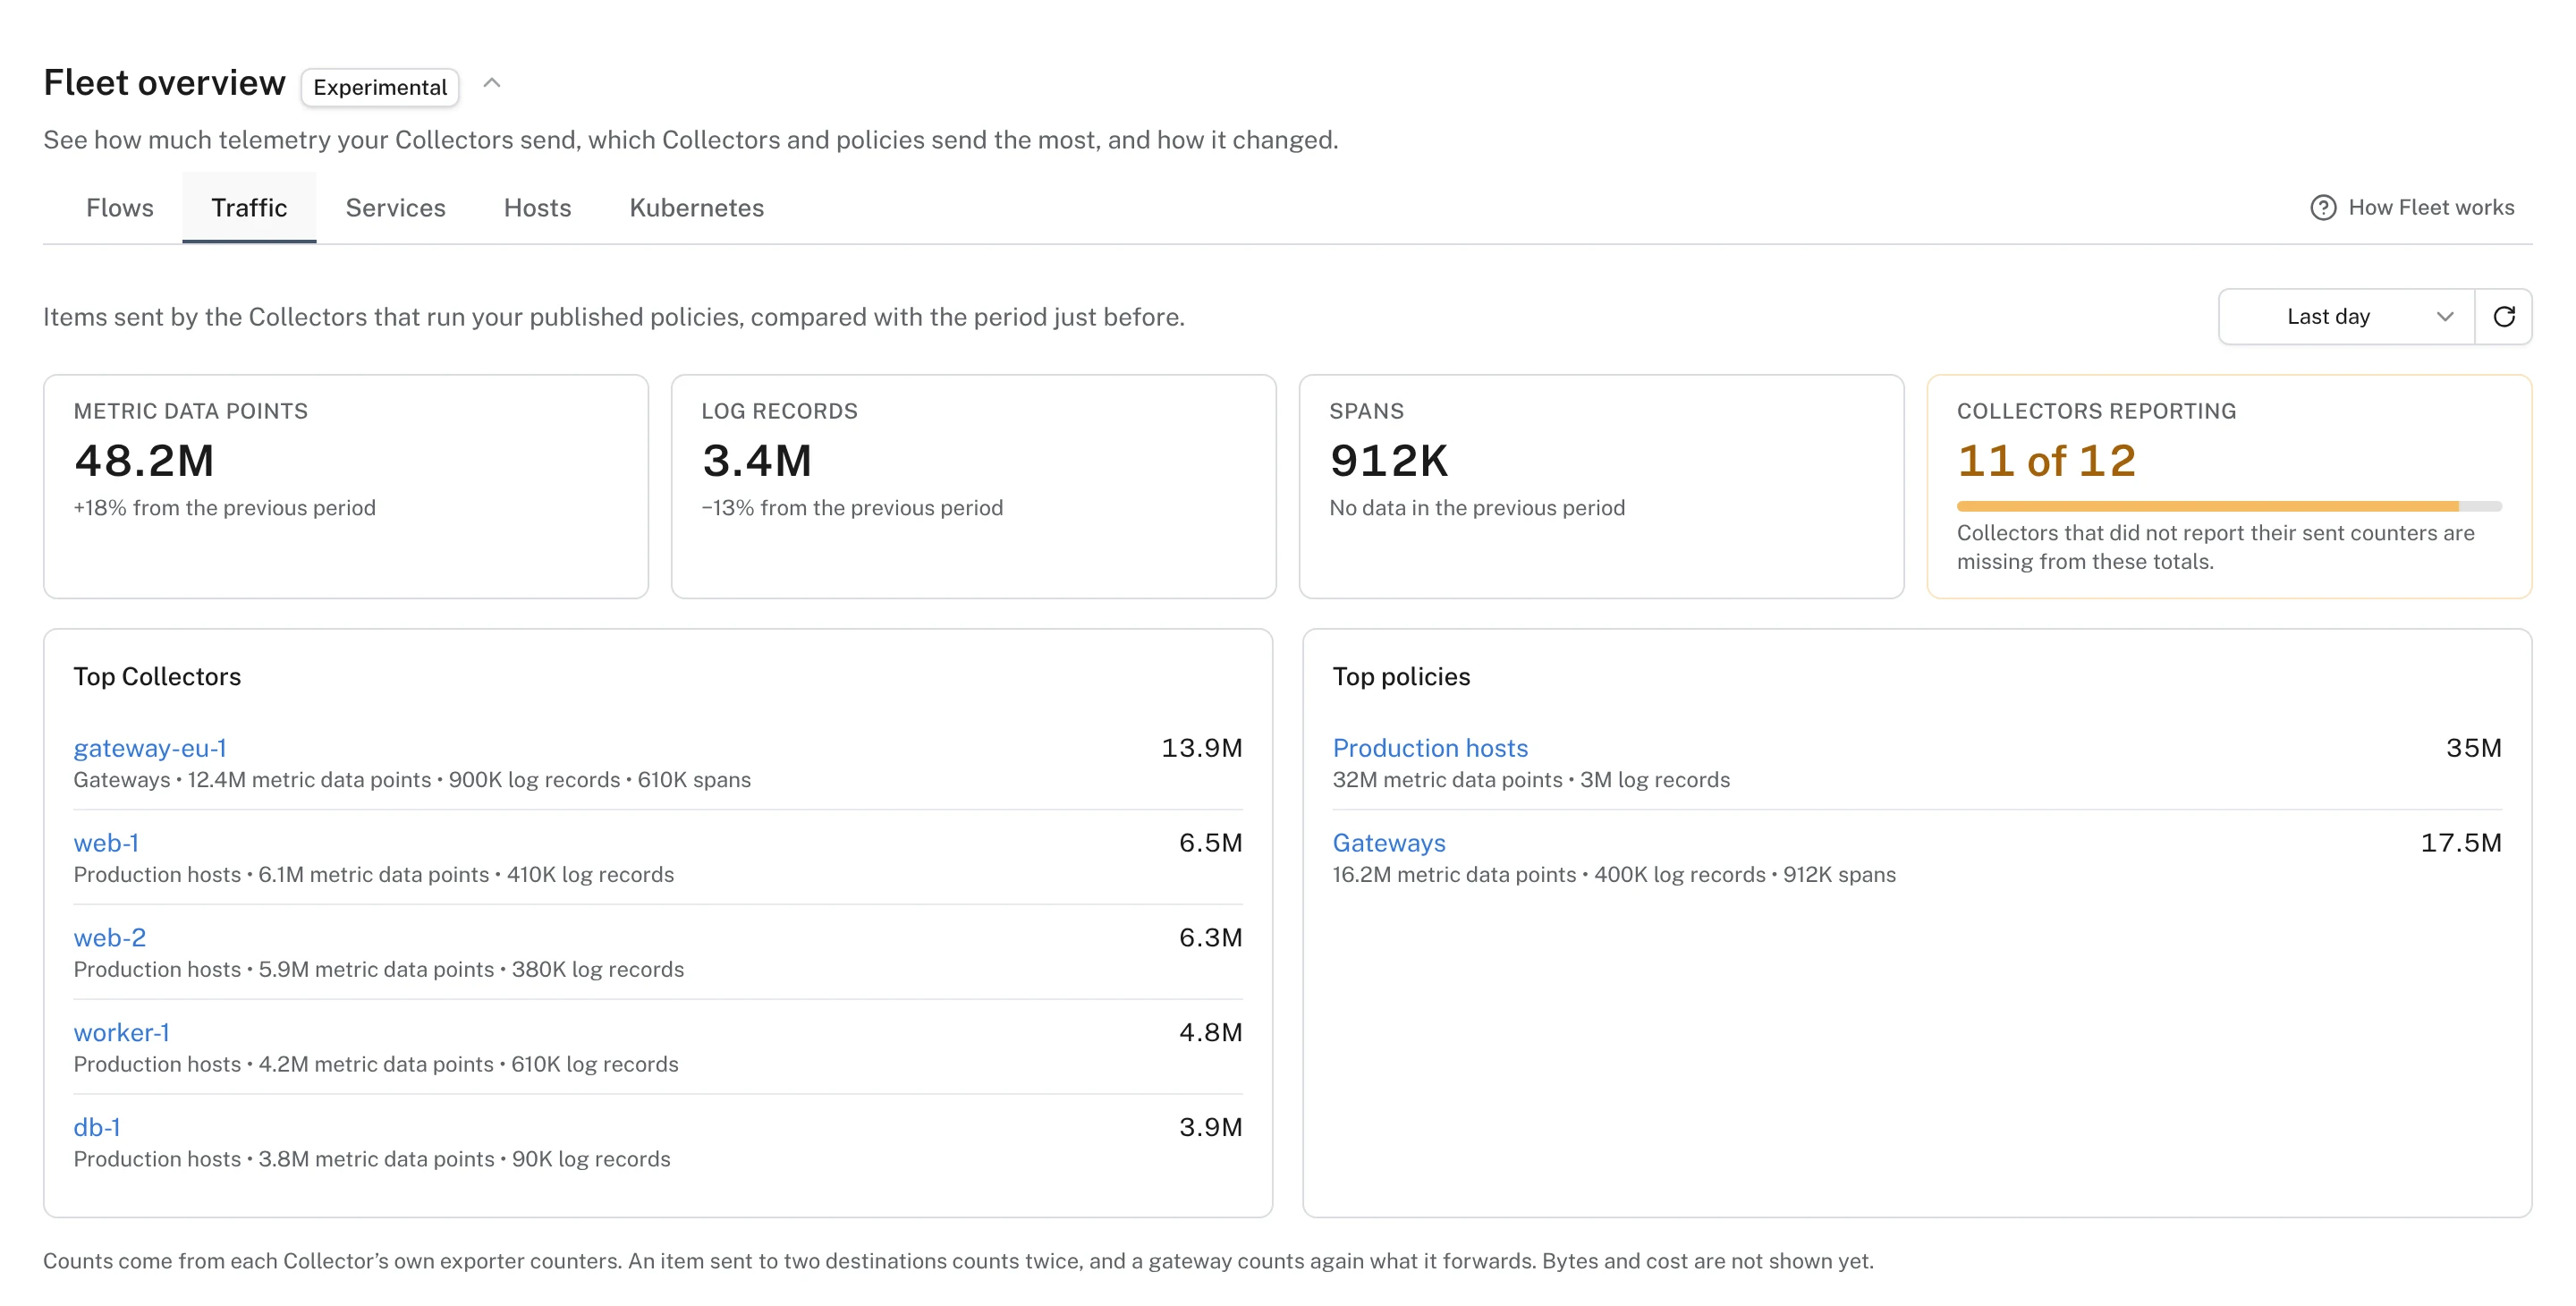
Collectors report their own exporter counters, so Fleet can total what each policy and each Collector sends, signal by signal, and compare it
with the period before. The policy that doubled your log volume overnight is at the top of the list.
Totals per signal, the top Collectors and policies, and how many Collectors reported. Open any of them to change the policy behind the number.
Open by design
Built on OpAMP and upstream OpenTelemetry
Fleet Management speaks the OpAMP specification. Host Collectors are upstream OpenTelemetry Collector builds, clusters connect through the
OpenTelemetry Operator's own bridge, and the application clients are public on GitHub.
A Collector policy is plain Collector YAML, so the destinations are yours to choose: Logfire, another OTLP backend, an archive, or all three.
Manage the agents in Logfire and send the data wherever it needs to go. If you ever stop using Fleet, the last configuration is still a file a
Collector can run.
Alongside
What the Collectors feed
Fleet manages the agents. Infrastructure monitoring covers what they collect: host, container and Kubernetes
views, database integrations, and the trace behind an unhealthy pod. Application performance monitoring covers the requests
running on top.
FAQ
Common questions
What is OpenTelemetry fleet management?
Managing the configuration of many telemetry agents from one place: OpenTelemetry Collectors on hosts and in clusters, and the SDKs inside your applications. Instead of editing a file on each machine or redeploying each service, you change a policy centrally and each agent applies it. It also means knowing what every agent is running and whether it is healthy.
What is OpAMP?
The Open Agent Management Protocol is the OpenTelemetry project's protocol for remote agent management. An agent connects to a server, describes itself, reports its health and effective configuration, and can receive new configuration, connection credentials and restart commands. Logfire Fleet Management is an OpAMP server, so it works with clients built to the specification as well as with our own.
Do I have to send my telemetry to Logfire?
No. A Collector policy is ordinary Collector configuration, so its destinations can be Logfire, another OTLP backend, a file archive, or several at once. An application policy governs the exporters the SDK sends through, whichever backend they point at. Fleet manages the agents; where they send data is up to you.
Can I keep my existing Collector configuration?
Yes. Paste it into a new Collector policy in YAML mode. The visual editor works on the same document, preserves comments and settings it does not recognize, and the publish review shows the exact diff before anything changes.
Which Collectors and clients are supported?
Host Collectors run the upstream OpenTelemetry Collector under an OpAMP Supervisor, which Logfire's command-line installer sets up. Kubernetes clusters connect through the OpenTelemetry Operator's OpAMP bridge. A Collector that only runs the upstream opamp extension reports its health and effective configuration but cannot take new configuration, because the extension does not accept it. Applications use the Logfire OpAMP clients for Python, Node.js, Go, Java and .NET.
How do applications pick up a new policy without a redeploy?
The OpAMP client in the application keeps a connection to Logfire. When a new application policy is published, the client applies it to the running SDK: the sampler and its rules, the rate caps, the exporters, the log levels, and the redaction and scrubbing rules. It reports back whether each setting applied, so the inventory shows which processes are on the new version.
How does Fleet keep telemetry costs under control?
Mostly by deciding inside each application what is never sent. An application policy sets the trace sampling rate and the rules in front of it, caps traces and log records per second, raises log levels and pauses signals, and running processes pick it up without a redeploy. For Collectors, the Traffic tab ranks each Collector and policy by what it sends, and the pipeline behind any of them is where you filter the excess out.
How do Collectors authenticate?
A host or cluster starts with an enrollment key. Clients that support it are then issued a connection key of their own, which can be rotated or revoked one client at a time without touching the others.
Is Fleet Management available on my plan?
Yes. Fleet Management is in Beta on every plan, including the free Personal plan. The pricing page lists the limits for each plan.
Manage your telemetry from one place
Start free with 10 million telemetry records per month. Fleet Management is included on every plan.